The Problem We’ve Been Living With
If you’ve spent any real time operating Kubernetes at scale, you know the sidecar injection story. Your service mesh—Istio, Linkerd, whatever you’re running—needs to inject networking proxies into your pods. The old way was a dance: an admission webhook intercepts pod creation, mutates the spec by adding init containers that set up iptables rules, and suddenly your pod startup time has degraded by 30 percent. On paper it works fine. In production at 3 AM when you’re debugging why your deployments take eight minutes instead of two, you start questioning life choices.
The hacky workarounds we’ve built around this are legendary. Some teams run dedicated node pools for mesh-heavy workloads. Others tune init container parallelization in ways that would make a SRE weep. We’ve all seen the pod that stays in Init:0/1 state for inexplicable lengths of time, and we’ve all held our breath waiting for the kubelet to finally decide it’s ready to move forward.
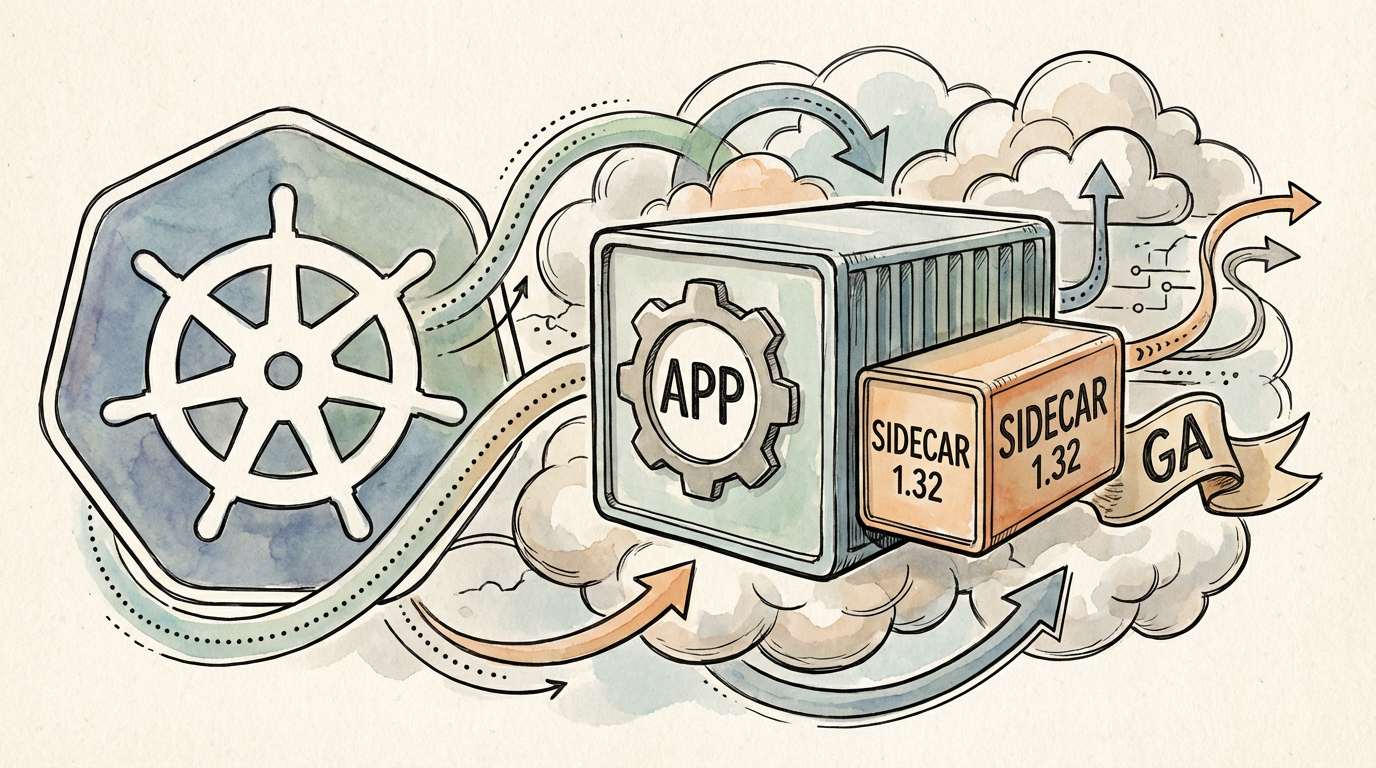
This is the context you need to appreciate what just shipped in Kubernetes 1.32, released in December 2024. The native sidecar container feature, which debuted as alpha back in Kubernetes 1.28 in August 2023, finally graduated to General Availability. That’s not a minor version bump. That’s a fundamental shift in how we can architect containerized workloads on Kubernetes.
How Native Sidecars Actually Work
The elegant bit is in the implementation. Instead of relying on admission webhooks to mutate your pod specs after the fact, native sidecars use a new field within the pod spec itself: `initContainers` with `restartPolicy: Always`. It’s the kind of simple architectural choice that makes you stop and think about why it took this long to get here.
The lifecycle is straightforward and predictable. Native sidecars start before your main application containers, just like traditional init containers. But here’s the critical difference: they don’t block the startup of your main containers. Your application comes up and starts accepting traffic while the sidecar is already running alongside it. And when your pod terminates, the sidecar gets a graceful shutdown window before the whole thing gets torn down. No more race conditions where your proxy gets killed mid-connection, or your application container exits while the sidecar is still draining.
You declare it in your manifest. No webhooks. No controller magic rewriting your YAML at runtime. Just explicit, declarative container lifecycle management. Infrastructure as code working the way it should.
The Numbers Actually Tell a Story
When a feature becomes GA, vendors immediately start publishing benchmarks. Some of those benchmarks are theater. But the ones coming out of the service mesh ecosystem are worth paying attention to because they’re solving real operational problems that teams have been complaining about for years.
The Istio team confirmed in their 2025 blog post that workloads using native sidecar support see pod startup latency reductions of up to 50 percent compared to the legacy webhook-based injection model, particularly in environments with high pod churn. That’s not a marginal improvement. That’s the difference between deployments that complete in five minutes and deployments that complete in ten—the difference between graceful blue-green deployments and noisy rolling updates that trigger alerts.
Linkerd’s benchmarks from early 2025 hit on something even more interesting: native sidecar lifecycle management eliminated an entire category of race-condition bugs responsible for roughly 8 percent of their reported production issues in 2024. These weren’t exotic edge cases. These were scenarios where the sidecar and main container got out of sync during shutdown, or where the proxy wasn’t fully initialized when traffic started flowing. The deterministic ordering of native sidecars makes these impossible by design.
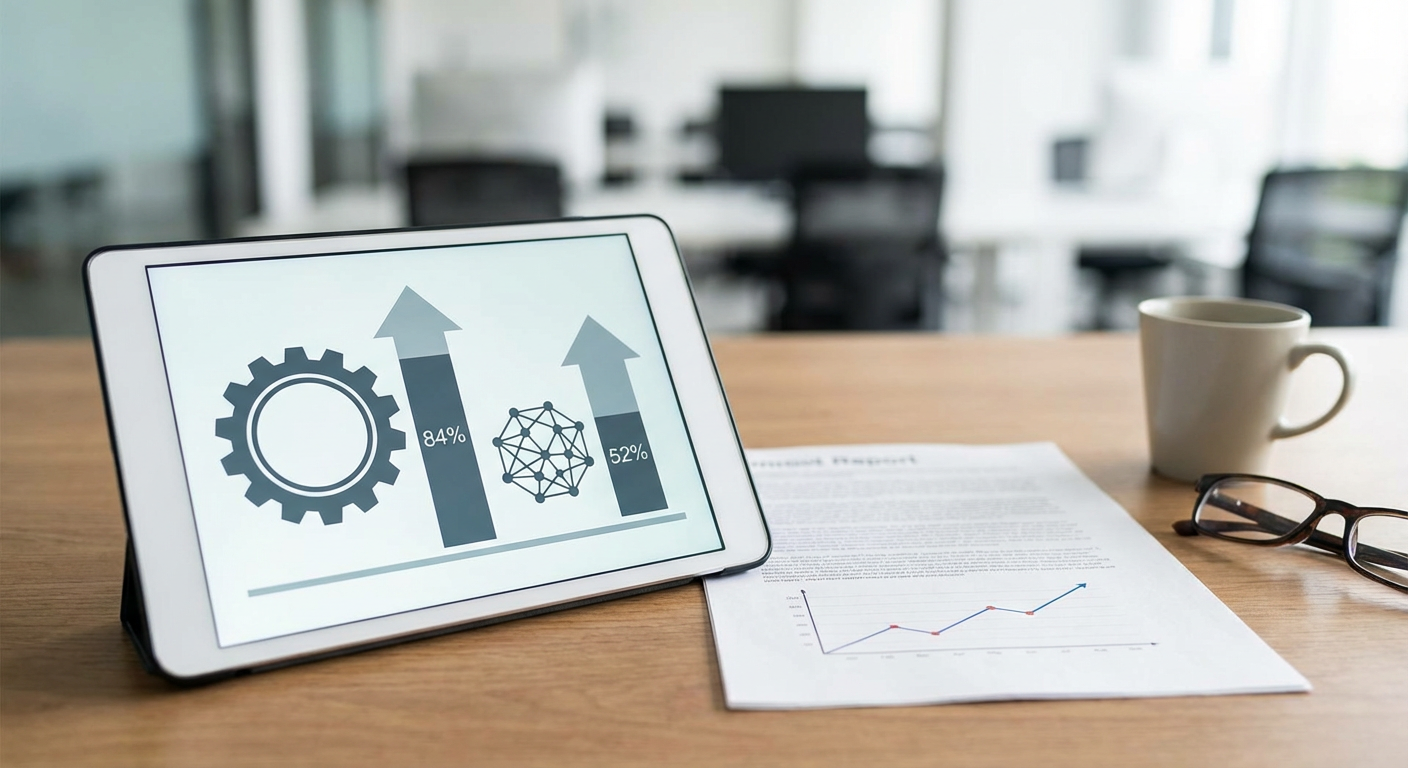
And the adoption context matters. According to the CNCF Annual Survey 2025, service mesh adoption has climbed to 52 percent of respondents running Kubernetes in production, up from 42 percent just two years prior. That’s 84 percent of survey respondents running Kubernetes at all. These aren’t fringe technologies anymore. Native sidecars are landing in an ecosystem where half of all production deployments might actually use them.
What This Means For Your Architecture
The shift from admission-webhook-based sidecar injection to native support changes the mental model in ways that aren’t immediately obvious. First, your pod specs become more honest. Everything that’s actually running is declared upfront. No more discovering hidden containers lurking in your admission controller logic when you’re debugging something at 2 AM.
Second, observability gets simpler. Tools can now reason about sidecar lifecycle without reverse-engineering webhook logic. Startup metrics become cleaner. You can actually correlate when your sidecar initialized with when your application started taking requests, instead of inferring it from indirect signals.
Third, and this is subtle but important, you get explicit control over sidecar behavior. You can apply different restart policies, resource limits, or security contexts to different sidecars in the same pod. The webhook model forced uniformity. Native sidecars let you be surgical.
For teams using service meshes, the implications are real. Mesh vendors can rely on predictable container lifecycle semantics instead of building workarounds on top of unreliable synchronization. Check the Kubernetes 1.32 Release Notes if you want to dig into the technical details, but the practical takeaway is simple: mesh injection is about to get materially faster and more reliable across the board.
The Bigger Picture
Native sidecars aren’t revolutionary in the sense that they enable entirely new use cases. But they do represent Kubernetes maturing in a specific way. The platform is moving toward explicit, declarative semantics for patterns that have been common practice for years. It’s cleaning up the technical debt that came from building infrastructure layers through webhooks and mutations.
This is the unglamorous work that makes the difference in production systems. Not the flashy new features that make headlines, but the careful refinement of core abstractions. The kind of work that means your deployments are faster, your bugs are fewer, and your on-call rotation can actually sleep through the night occasionally.
If you’re running Kubernetes in production, native sidecars are worth understanding whether or not you’ve adopted a service mesh yet. Explore what your mesh vendor has published. Run benchmarks against your actual workloads. The performance gains might surprise you. I’d be curious to hear what you find in your environment—these kinds of measurements are almost always more interesting when they come from real production systems rather than the generic labs where benchmarks usually live.